

Voice First Coding Harness
The speed of building now depends on how many agents you can handle.
The models are fast enough. The limit is you — how many agents you can keep moving in parallel without losing track of any of them.
More code, faster, than anyone can read. Skimming is hoping.
Five agents, one pair of eyes. While you read one, the other four wait for you.
"Delete the test file" / "delete the rest of the file." A misheard word executes.
One harness for every agent, every project, every language.
Talk to it, hear it talk back, and let it run the rest — on any model, with git built in.
Real-time talkback while you pace, sketch or make coffee. Ask for a change, hear what happened, answer the next question — without going back to the keyboard.

Give instructions in your own language, or mix two. SKI works out what you meant and hands the agent a precise instruction.
"login वाले tests फिर से चलाओ"
"vuelve a correr los tests de login"
"ログインのテストをもう一度実行して"
Rerun the login test suite
An intelligent orchestration layer keeps the context of every project, branch and chat. Ask where things stand and get one spoken answer — then let it hand each job to the right agent.
Bring the accounts you already pay for and pick the engine per task. When the leaderboard changes, your workflow stays.
Claude Code, Codex, Antigravity and OpenCode side by side, each on its own task. You hear the moment any one of them needs you.
Every chat gets its own branch and worktree, so agents never step on each other. Watch the diff as it happens, then say "open the PR".
"Open the PR."✓ PR #142 opened
You find out what your agents did by listening, not reading.
Results, summaries, the moment something needs you — spoken while you keep working.
The moment an agent needs you, it tells you.
A blocked agent announces itself. You answer in a sentence and it keeps going.
What you meant is what runs — anything irreversible asks first.
SKI rebuilds the instruction from your project, shows you the interpretation, and gates anything irreversible.
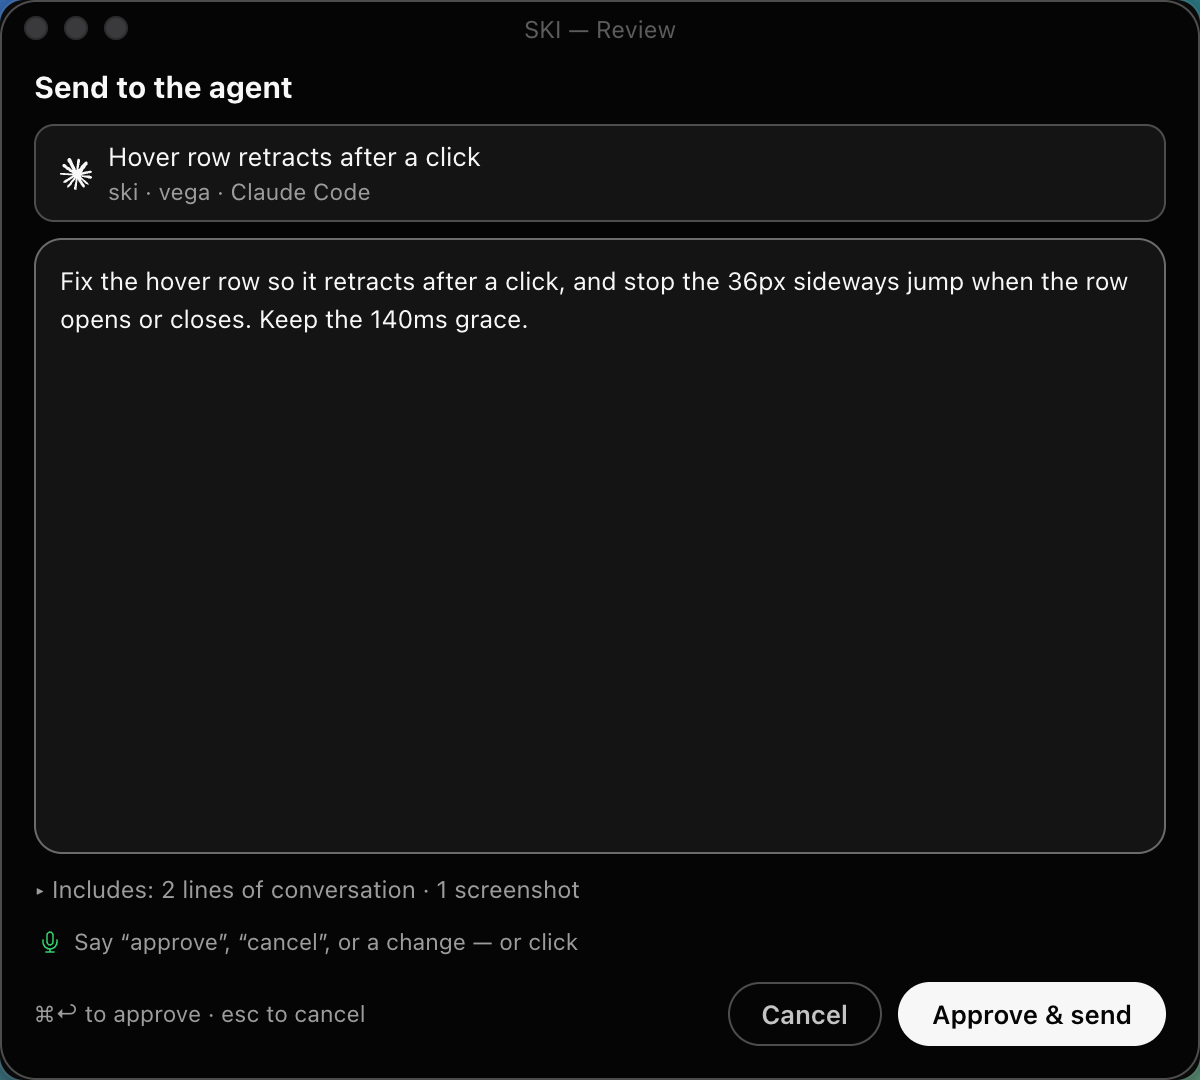
From project context, not raw transcription.
You correct it before the agent ever sees it.
Routine work runs. Destructive work asks.

Run every engine you already pay for, and send each job to the right one.
Hard reasoning to the expensive engine, bulk work to a cheap open-weight one. Spend follows the job, not the vendor.
A harness built for typing assumes you are watching the screen.
A reply is expected in ~200 ms; an agent turn runs ~45 s. A fast layer holds the conversation while the slow work runs.
You type composed prompts. You speak messy ones. The harness works out the intent — and asks instead of guessing.
Repair is designed in from the start, not bolted on after a bad transcription.
None of this can be retrofitted with a microphone.
Your code stays on your Mac.
Your projects, code and chats stay on your Mac, and your agents run on your own accounts. Your voice goes through the cloud to be understood and answered — it isn't stored.

Every agent, every state, on one canvas.
Leads, workers, and what each one is doing right now — you hear the moment any of them needs you.

Start alone. Bring the team when they ask.
Start on your own card. Team and Enterprise exist because colleagues ask.
Your own card, no approval, no sales call. Good enough to keep — not a crippled trial.
Shared setup, a company invoice, and nothing else in the way.
On your team's Macs — never through us. Admin controls for the whole team.
Is this dictation?
No. Dictation hands text to somebody else's harness. SKI is the harness — the whole loop runs on voice.
Isn't talking slower than typing?
Often, yes. The win is not the input — it is that you stop reading output and hear the moment an agent is blocked.
How is this different from an orchestrator?
They orchestrate by clicking. Ask any of them: how do you steer an agent when you are not looking at the screen?
Which agents and models does it work with?
Whichever ones you already run. Neutrality is the point.
What happens if it mishears me?
You see the interpretation before it runs, and anything irreversible asks first.
Do I have to talk to a salesperson?
No. Get SKI, install, start.
Pick your platform.
Not out yet. Leave your email and we'll write when it is.
The coding harness you talk to. Run every agent you already use — and hear them, instead of reading them.